Fault Injection
Rift enables fault injection for chaos engineering and resilience testing.
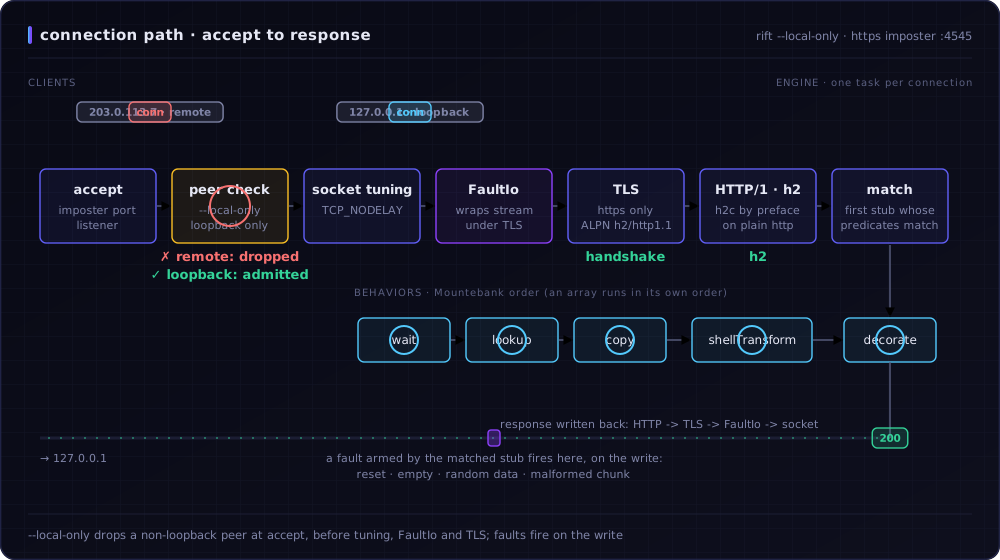
Mountebank Behaviors
Latency with wait Behavior
{
  "stubs": [{
    "predicates": [{ "equals": { "path": "/api/slow" } }],
    "responses": [{
      "is": { "statusCode": 200, "body": "OK" },
      "_behaviors": { "wait": 2000 }
    }]
  }]
}
Random Latency
A wait can be a JavaScript function returning the delay in milliseconds. Two spellings are
accepted, and both execute identically:
{
  "_behaviors": {
    "wait": {
      "inject": "function() { return Math.floor(Math.random() * 1000) + 500; }"
    }
  }
}
The bare string is the Mountebank-compatible spelling — use it if the same config must also run
on Mountebank. The {"inject": ...} object is Rift's spelling, used by the SDKs; like the
{"min": N, "max": M} range below, it is a Rift extension with no Mountebank equivalent, so a
config using it is not portable to Mountebank. Rift accepts either and preserves whichever you
wrote when you read the imposter back.
A function wait requires --allowInjection (either spelling), the same as Mountebank — without
it, creating the imposter returns 400 invalid injection.
That gate applies to every door an imposter can arrive through, not just the admin API (issue
612): a --configfile carrying a function wait aborts startup naming the offending port, a
--datadir file carrying one is skipped and listed in the startup skip summary, and
POST /admin/reload returns 400 invalid injection and leaves the running imposters unchanged.
So examples/latency-testing.json needs --allowInjection however you load it.
For a simple random range with no JavaScript, use the range form instead:
min must be no greater than max. An inverted range has no delay to draw from, so it is
refused at every door — POST/PUT /imposters, the stub endpoints, --configfile, --datadir
and POST /admin/reload — with a 400 naming both values; rift-lint reports it as E025 before
the engine ever sees the file. min == max is a valid inclusive range meaning a fixed delay. The
stub-level delayRange is the same range in a different place and follows the same rule.
Upgrade note: before Rift 0.18.0 an inverted range was accepted and then dropped every connection
to that stub. A --datadir holding one now fails to load rather than serving a broken stub.
Error Responses
{
  "stubs": [{
    "predicates": [{ "equals": { "path": "/api/error" } }],
    "responses": [{
      "is": {
        "statusCode": 500,
        "body": { "error": "Internal Server Error" }
      }
    }]
  }]
}
Probabilistic Errors with Injection
{
  "stubs": [{
    "responses": [{
      "inject": "function(config) { if (Math.random() < 0.1) { return { statusCode: 500, body: 'Random failure' }; } return { statusCode: 200, body: 'Success' }; }"
    }]
  }]
}
Rift Extensions (_rift.fault)
Probabilistic Latency
{
  "port": 4545,
  "protocol": "http",
  "stubs": [{
    "predicates": [{ "startsWith": { "path": "/api" } }],
    "responses": [{
      "is": { "statusCode": 200, "body": "OK" },
      "_rift": {
        "fault": {
          "latency": {
            "probability": 0.3,
            "minMs": 100,
            "maxMs": 500
          }
        }
      }
    }]
  }]
}
Fixed Latency
Probabilistic Errors
{
  "stubs": [{
    "predicates": [{ "equals": { "method": "POST" } }],
    "responses": [{
      "is": { "statusCode": 200, "body": "OK" },
      "_rift": {
        "fault": {
          "error": {
            "probability": 0.1,
            "status": 503,
            "body": "{\"error\": \"Service Unavailable\"}",
            "headers": {
              "Retry-After": "30"
            }
          }
        }
      }
    }]
  }]
}
Field reference
| Block | Field | Default | Notes |
|---|---|---|---|
latency |
probability |
1.0 |
Firing chance, 0.0–1.0. |
latency |
ms |
— | Fixed delay. When set, it is used instead of minMs/maxMs. |
latency |
minMs / maxMs |
0 |
Random delay range, in milliseconds. |
error |
probability |
1.0 |
Firing chance, 0.0–1.0. |
error |
status |
503 |
Status of the injected response. |
error |
body |
none | A string; JSON must be written as an escaped string, as above. |
error |
headers |
none | Name to string value. Each header may be named only once, compared case-insensitively — {"Retry-After": "1", "retry-after": "2"} is rejected when the imposter is created rather than sending the header twice. |
tcp |
string or {probability, type} |
— | See TCP Faults. |
Combined Faults
Apply both latency and errors:
{
  "responses": [{
    "is": { "statusCode": 200, "body": "OK" },
    "_rift": {
      "fault": {
        "latency": {
          "probability": 0.5,
          "minMs": 200,
          "maxMs": 1000
        },
        "error": {
          "probability": 0.05,
          "status": 500
        }
      }
    }
  }]
}
A _rift block on its own, as in the fragments on this page, is a complete response: it is served
as is: {} — an empty 200 (completed by defaultResponse, if the imposter has one) — whenever
the fault does not fire. Pair it with an is to set the normal answer.
TCP Faults
Simulate network-level failures. Unlike a script, none of _rift.fault needs
--allowInjection — it is data, not code.
TCP fault types (each accepts a WireMock-style canonical name or a short alias):
| Fault | Aliases | Effect |
|---|---|---|
CONNECTION_RESET_BY_PEER |
reset |
Real TCP reset (RST) — the connection is aborted |
EMPTY_RESPONSE |
empty |
Close the connection with no bytes sent |
RANDOM_DATA_THEN_CLOSE |
random, garbage |
Write random bytes, then close |
MALFORMED_RESPONSE_CHUNK |
malformed |
Send a status line + a malformed chunked body, then close |
Probabilistic TCP faults
The bare string form above always fires. To reset only some of the time, use the object form,
which carries a firing probability (0.0–1.0) alongside the fault type:
This resets the connection on ~10% of requests and serves the normal response the rest of the time,
mirroring the probability roll latency and error already use. probability is required in
the object form — { "type": ... } with no probability is rejected; use the bare string form for an
always-firing fault. The bare form is exactly equivalent to the object form with probability: 1.0,
and each form round-trips unchanged through GET /imposters (a string stays a string, an object
stays an object).
These are real transport-level events, so HTTPS imposters get them too. A reset and an empty
response act on the socket beneath TLS. Random data and a malformed chunk are sent inside TLS: an
HTTPS client completes the handshake, decrypts the bytes and then fails to parse HTTP, as with
Mountebank. Because a connection-level fault aborts the whole socket, an imposter that uses any TCP
fault is advertised and served over HTTP/1 only (HTTP/2 multiplexing is incompatible with
mid-stream connection aborts). On HTTPS that means the TLS handshake offers only http/1.1, so an
h2-capable client is never led to commit to a protocol the imposter will not speak.
The same faults fire through the single-port gateway (/__rift/{port}/… on the admin
port) and the front door. Over HTTP/1 the client sees exactly what the
imposter's own port would give it: a reset, an empty reply, garbage bytes, or a 200 head followed
by a broken chunk. Those two listeners are shared by every imposter (and the admin API), so they
keep negotiating HTTP/2; there a TCP fault resets that one stream (RST_STREAM with
INTERNAL_ERROR, for every fault kind) and leaves the connection and its other streams working.
Aborting the socket would take down every request multiplexed on it.
A reset is abrupt, and that includes data still on its way. A client that pipelines a request past a
faulted one and reads slowly can lose the tail of the earlier response: SO_LINGER(0) discards what
the kernel has not yet sent. An empty response behaves similarly: bytes the client pipelined behind the
faulted request are left unread, so the kernel may turn the close into a reset.
With recordRequests: true the faulted request is journaled with its matchOutcome but without
status or latencyMs, since no response was sent. This holds for every TCP fault: _rift.fault.tcp,
a top-level fault and a script's reset(), and for every door the request came through.
Top-Level Fault Response (Mountebank Parity)
Mountebank lets a stub response be a bare fault instead of an is/proxy/inject body. Rift
supports the same shape, and a top-level fault resets the connection at the transport level,
matching Mountebank's transport-fault semantics:
{
  "stubs": [{
    "predicates": [{ "equals": { "path": "/api/flaky" } }],
    "responses": [{
      "fault": "CONNECTION_RESET_BY_PEER"
    }]
  }]
}
A client hitting this stub sees a transport error (connection reset), not a response. The recognized
fault strings are the same set as _rift.fault.tcp above (CONNECTION_RESET_BY_PEER,
EMPTY_RESPONSE, RANDOM_DATA_THEN_CLOSE, MALFORMED_RESPONSE_CHUNK, plus their aliases). An
unrecognized fault string is ignored, as in Mountebank: no fault fires, and the stub answers an
empty response completed by the imposter's defaultResponse (else 200 with an empty body), with
no x-rift-fault header. Rift warns when the imposter loads, and rift-lint reports it as
W022.
Like _rift.fault.tcp, a bare top-level fault also forces the whole imposter onto HTTP/1
only: it is a connection-level event, and aborting a socket mid-stream is incompatible with
HTTP/2 multiplexing — so an imposter with even one stub returning a top-level fault never
negotiates HTTP/2, regardless of what its other stubs do.
Detecting a fault in-process (embedders)
A TCP fault never reaches the wire as a response. Rift builds a placeholder carrier response and the listener that owns the socket (the imposter's own port, the gateway, the front door) aborts it instead of sending it, so a client over TCP observes only the transport error described above.
A Rust program embedding the engine and calling handle_imposter_request directly — answering a
"try this imposter" request in-process, with no socket involved — receives that carrier instead, and
would otherwise present its 502 as the imposter's answer. Classify it with tcp_fault_carrier:
use rift_mock_core::imposter::handle_imposter_request;
use rift_mock_core::tcp_fault_carrier;

let response = handle_imposter_request(req, imposter, addr).await?;

match tcp_fault_carrier(&response) {
    // The connection would have been aborted; there is no response to show.
    Some(fault) => println!("connection aborted: {fault}"),
    None => println!("status {}", response.status()),
}
It returns the canonical fault name (CONNECTION_RESET_BY_PEER, …) whatever alias the config
used, for all three ways a fault is expressed — _rift.fault.tcp, a top-level fault, and a
script's reset().
To branch per fault, read the TcpFaultKind extension instead. It is #[non_exhaustive], so match
with a _ arm — a future transport fault must not break your build:
use rift_mock_core::TcpFaultKind;

match response.extensions().get::<TcpFaultKind>() {
    Some(TcpFaultKind::Reset) => { /* RST */ }
    Some(TcpFaultKind::Empty) => { /* closed with no bytes */ }
    Some(_) => { /* some other transport fault */ }
    None => { /* an ordinary response */ }
}
Do not classify on the x-rift-fault header: it echoes the raw configured string rather than the
canonical name, and _rift.fault.error also sets it on a response the client genuinely receives.
Serving from your own listener
A listener you own that forwards to an imposter (with dispatch_to_port or
handle_imposter_request) can apply the fault the way Rift's own listeners do, instead of
classifying it. Wrap each accepted TcpStream in FaultIo with a fresh FaultCell, before any
protocol detection, and pass every finished response through apply_tcp_fault together with the
request's HTTP version:
use rift_http_proxy::gateway::{apply_tcp_fault, dispatch_to_port};
use rift_http_proxy::{FaultCell, FaultIo, arm_linger_if_requested};

let cell = FaultCell::new();
let io = TokioIo::new(FaultIo::new(stream, cell.clone()));
let service = service_fn(move |req| {
    let (manager, cell) = (manager.clone(), cell.clone());
    async move {
        let version = req.version();
        let response = dispatch_to_port(&manager, port, req).await;
        // A body refusal closes cleanly instead of resetting under the 413 (issue #1460).
        arm_linger_if_requested(&response, version, &cell);
        apply_tcp_fault(response, version, &cell) // Result<_, InjectedFault>
    }
});
On HTTP/1 apply_tcp_fault arms the cell and returns the carrier, and FaultIo performs the fault
when hyper writes it. On HTTP/2 it returns Err(InjectedFault), which your service returns so hyper
resets that stream. The connection error hyper then reports on HTTP/1 is the fault you asked for,
not a failure: is_injected_fault(&err) tells the two apart, so you can log it below error.
Fault Precedence
When a single _rift.fault block combines latency, tcp, and error, they are evaluated in
this order:
latency— applied first (the response is delayed), then evaluation continues.tcp— if it fires, the connection is reset and no HTTP response is sent. Atcpfault is a transport-level event, so it takes precedence overerror.error— applied only when notcpfault fired.
So latency + tcp is a delay-then-drop, and a configured tcp fault always wins over an
error fault rather than being silently dropped.
One response type per response
_rift.fault and a top-level fault string live on different response shapes. A stub response
carries exactly one of is, proxy, inject and fault: one with two, such as an is block
and a top-level "fault" string, is refused with 400 and
each response object must have only one response type, as Mountebank refuses it. A null or an
empty "" value counts as absent, as it does in Mountebank. To combine a status, headers or a body
with a transport fault, put _rift.fault inside the is block; for the transport fault alone, use
a bare fault.
Earlier releases kept the first of is > proxy > inject > fault and silently dropped the
rest. A config an engine already stored (--datadir, an embedder's log) still loads that way.
Scripted Faults
Scripted faults need --allowInjection: a _rift.script is gated the same way as inject.
For dynamic fault injection based on request data or state, use the scripting feature. Full
reference (the unified ctx object, result constructors, and what runs where) lives on the
Scripting page; this section just shows it applied to fault injection.
Rhai Script - Retry Simulation
Fail the first 2 requests, pass through on the 3rd. Bare-expression form: the whole script body is
the respond(ctx) function, with ctx already in scope, and http(status, body) replaces a
hand-built #{ inject:, fault: } map:
{
  "port": 4545,
  "protocol": "http",
  "_rift": {
    "flowState": {"ttlSeconds": 300}
  },
  "stubs": [{
    "responses": [{
      "_rift": {
        "script": {
          "engine": "rhai",
          "code": "let n = ctx.state.incr(\"attempts\"); if n <= 2 { http(503, #{ error: \"Temporary failure\", attempt: n }) } else { pass() }"
        }
      }
    }]
  }]
}
Script Return Values
respond(ctx) returns a result constructor — see Scripting
for the full reference. The shapes used above, restated:
Rhai:
// No injection - pass through
pass()

// Inject error
http(503, #{ error: "Service unavailable" })

// Inject latency
delay(500)

// Reset the connection (same carrier as a TCP fault)
reset()
A script-decided fault is counted in the same Prometheus families as a _rift.fault one, with
source="script" — see Metrics.
Use Cases
Testing Timeout Handling
{
  "predicates": [{ "equals": { "path": "/api/external-service" } }],
  "responses": [{
    "is": { "statusCode": 200, "body": "OK" },
    "_rift": {
      "fault": {
        "latency": {
          "probability": 1.0,
          "ms": 35000
        }
      }
    }
  }]
}
Testing Retry Logic
Use scripting to fail a specific number of requests before succeeding:
{
  "port": 4545,
  "protocol": "http",
  "_rift": {
    "flowState": {"ttlSeconds": 300, "flowIdSource": "header:X-Request-Id"}
  },
  "stubs": [{
    "predicates": [{ "equals": { "path": "/api/resource" } }],
    "responses": [{
      "_rift": {
        "script": {
          "engine": "rhai",
          "code": "let attempts = ctx.state.incr(\"attempts\"); if attempts <= 2 { http(503, #{ error: \"Retry later\", attempt: attempts }).header(\"Retry-After\", \"1\") } else { pass() }"
        }
      }
    }]
  }]
}
Testing Circuit Breaker
Simulate random failures:
{
  "_rift": {
    "fault": {
      "error": {
        "probability": 0.5,
        "status": 500,
        "body": "{\"error\": \"Service failure\"}"
      }
    }
  }
}
Best Practices
- Start with low probability - Begin at 1-5% and increase gradually
- Use specific matches - Target specific endpoints, not all traffic
- Add identifiers - Include headers to identify injected faults
- Monitor metrics - Track fault injection rate and impact
- Test in staging first - Validate fault scenarios before production
- Document scenarios - Keep a runbook of chaos experiments
- Use flow_id for isolation - Namespace state by request/user ID to avoid cross-contamination